
On October 31, 2026, the DeepSeek Harness team published a design essay, Exploring Super-agent Design: Towards a More Autonomous Agent System, together with an MIT-licensed research prototype called dsh-superagent-prototype. It is not a new model. It is a proposal for the system that sits around the model.
My verdict in one line: the architecture is worth stealing, the code is worth reading, and nobody in a bank should run it as is.
Half the posts I read this week mix up three different things. “DeepSeek SuperAgent Harness” is the label the community stuck on the combination, but the layers matter if you want to evaluate any of it.
| Name | What it is | Released |
|---|---|---|
| DeepSeek Harness (DSH) | Open-source, MIT-licensed coding agent runtime. Everything is a plugin, including the agent loop, on top of a composability framework called Cordis. Works with other providers and OpenAI-compatible endpoints. | August 13, 2026, alongside DeepSeek V4 Pro |
| Super-agent design essay | An architecture proposal for an always-on, multi-task agent system. Credited to Yujia Qiao on behalf of the Harness team. | October 31, 2026 (WeChat and X) |
| dsh-superagent-prototype | TypeScript bundle v0.1.0 that runs as a dedicated DSH profile. One GitHub repository, optional Feishu, a local web panel. | October 31, 2026 |
The prototype is not a fork. It is a set of DSH plugins: a core Super Agent plugin, a GitHub watcher and a Feishu watcher, wired in through a Cordis patch file, plus stripped-down Router and Worker presets.
One caveat I will keep coming back to. The README says the public code differs from DeepSeek’s internal system, and that some designs in the essay are future directions, not features. In this article, “the design” means the ambition and “the prototype” means the code. I label which is which.
DeepSeek’s starting point is something every heavy user of Claude Code, Codex or Copilot agent mode already feels. One agent fixing one bug is solved. Ten agents on ten tickets is a different job, and that job lands on you.
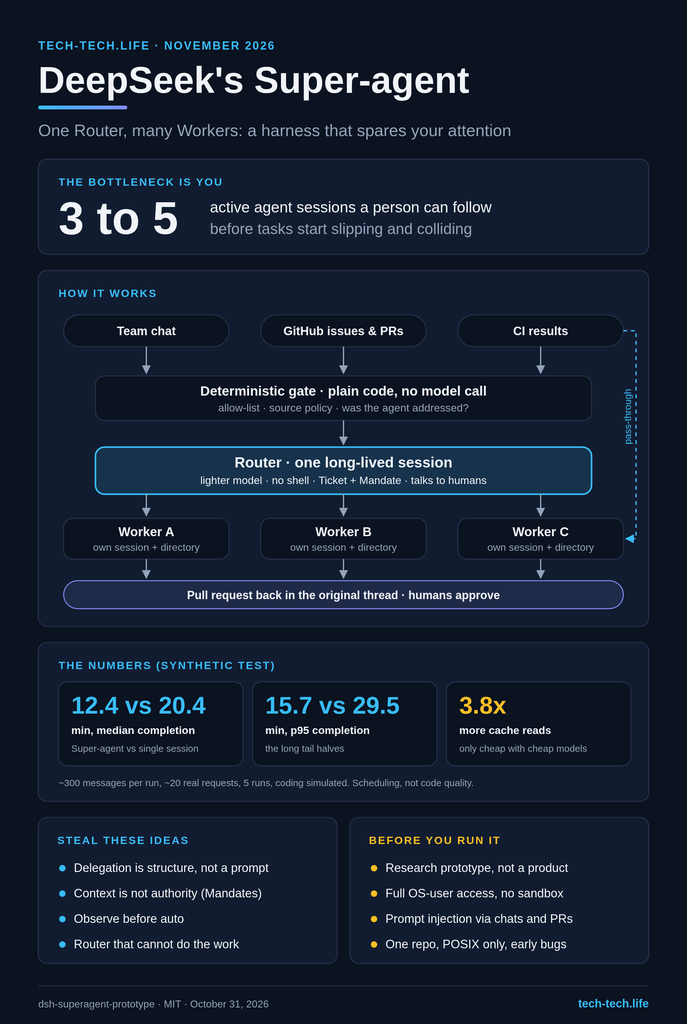
The team’s observation is that a person can follow roughly three to five active sessions before things slip. You forget which session is waiting for an approval, which one is stuck in a loop, and which two are quietly editing the same pull request. It is a field observation, not a measured law, but I have never met a developer who disagreed with it.
The essay frames four goals for an agent system that removes this load:
The principle the prototype puts in its README says it best: take as little human attention as possible, and give as much value as possible. I would print that on the wall of any team building internal agents.
The design rejects both obvious options. Push every event into one giant session and you get shared context, but the session does one thing at a time and unrelated tasks bleed into each other. Spawn a fresh session per event and you get speed, but no continuity, and several agents answering you at once.
The compromise has two layers.
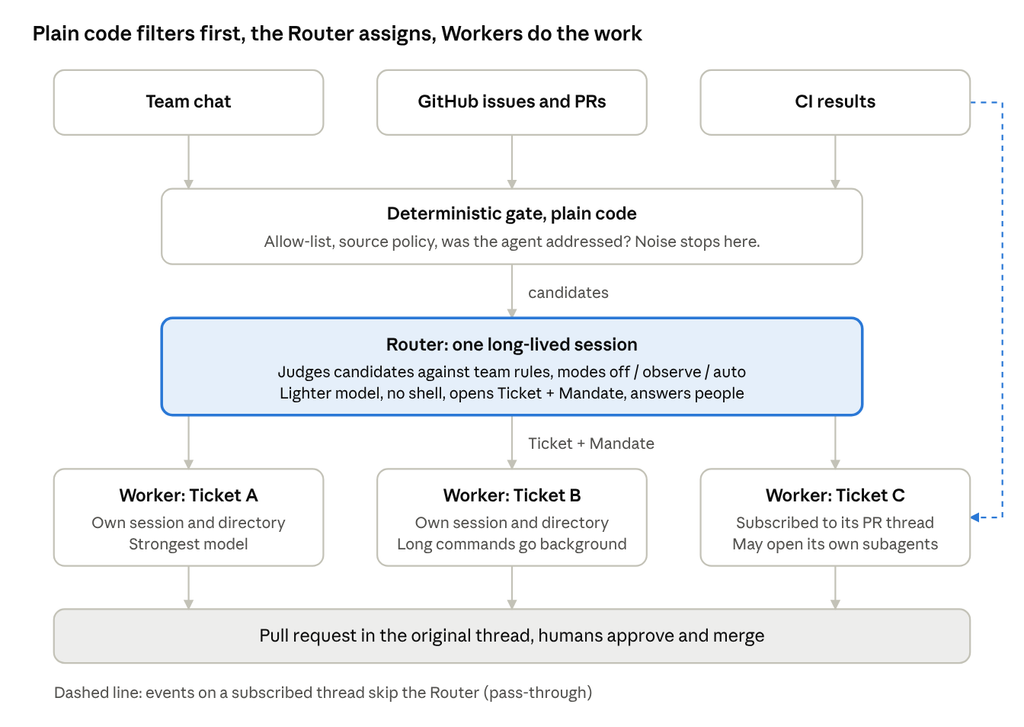
Every event crosses a cheap code gate before any model sees it. Once a Worker owns a thread, later events on it skip the Router.
This inverts a habit I see in most enterprise agent pilots, where the “orchestrator” gets the premium model. DeepSeek’s Router does not decompose problems. It assigns and tracks. That is a cheaper job.
An always-on agent receives far more input than direct requests. Chat messages, PR comments, CI results and calendar reminders all become Triggers, and most of them deserve nothing.
Related events are grouped into Threads: a PR and its review comments, a chat topic and its replies. Once a Worker owns a Ticket, it subscribes to the Thread, and later events go straight to that Worker by code, without a new routing decision. DeepSeek calls this pass-through. Subscriptions are many-to-many, so two Workers on the same PR see the same events. That gives them a chance to notice a conflict. It is not a lock.
The essay borrows two ideas from computer systems. Inline puts likely-useful material straight into context: nearby messages, a reply’s parent, neighbouring review comments. Spill keeps the rest outside, behind a short summary and an ID that can be expanded later.
Because events, Threads and sessions all reference each other by ID, the Router can walk from a new comment to its Thread, from the Thread to a Worker session, and from there to a discussion from weeks ago. DeepSeek calls this the chain of recall. It is a retrieval path, not a guarantee that the model picks the right history. The team itself lists long-term memory as unsolved.
This is the part I found most mature, and it is where the prototype is more careful than the hype around it.
Context is not authority. In the prototype’s authorization model, the host enforces allow-lists, rules and Mandates. Messages, comments and quoted documents are inputs to a decision. They cannot change permissions. A comment arriving on a subscribed Thread reaches the Worker as context and grants nothing new.
Three acceptance modes for proactive work:
| Mode | What happens to inferred work (unaddressed messages, bot messages, follow-ups from people not on the list) |
|---|---|
off | Nothing inferred becomes a candidate |
observe (default) | Candidates are assessed, and a positive result is logged as “would accept”. Nothing runs. |
auto | A positive assessment accepts the work |
Explicit requests from allowed people work in every mode. The documented advice is to start in observe, read the logged decisions, and only then switch to auto. DeepSeek reportedly ran its own internal deployment the same way. If you take one thing from this release into your own agent platform, take this.
A few more details worth knowing:
Silent reproduce-and-fix. Internally, DeepSeek uses a policy where a bug reported in a chat is reproduced in the background. If the agent confirms the bug and finds a fix, a pull request shows up while the conversation is still going. If not, nobody hears about it. Speculative work costs compute, but it is cheap to throw away. A posted comment or a merged change is not, which is why the authorization boundary sits there.
Long commands should not hold the conversation hostage. In the design, a tool can start a background job, hand control back to the agent loop, and deliver its result later as an event. The team calls this full-duplex: you can send a correction while a ten-minute build runs. In the prototype, any shell command still running after five seconds moves to the background, so a Worker keeps receiving messages. The essay notes that the general async mechanism exists in DSH but was not on by default.
Separate the agent from its machines. A local agent usually ties three things together: the compute running the loop, the session state and the environment where commands execute. Close the laptop and all three disappear. The design pulls them apart in two steps. State lives in persistent storage, so the loop can restart anywhere. Then the loop reaches execution environments through light endpoint daemons. DeepSeek calls this Bring Your Own Machine: your laptop, with its uncommitted changes, its GPU, its intranet access, becomes one endpoint among cloud sandboxes. The team credits Anthropic’s managed-agents work for the brain/hands split and puts its own emphasis on personal machines with intermittent connectivity. To be clear, this is design, not something the prototype ships.
A Watchdog for agents that are alive but stuck. A process can run and make zero progress: retrying the same failing command, losing track of its task, waiting on a dead dependency. The design proposes a separate agent session, woken on a schedule, that checks infrastructure, judges whether Workers are progressing, and attempts repairs. No detection or repair rates are given. The prototype only documents an external hourly status-and-recovery check, which is far narrower.
Communication discipline. The team reports that capping instant-message replies at about 100 words worked well for them, while PRs carry the full context. Detail goes where it belongs, and chat stays for decisions.
The Super-agent finished simulated tasks about 39% faster at the median than a single session, at about 3.8 times the cache reads. Read the setup before you quote that.
Each run fed about 300 group-chat and CI messages, roughly 20 of them real work requests, the rest chatter, follow-ups and cancellations. Four designs, five runs each. The coding itself was simulated by a tool that just consumed time, and message intervals and work durations were scaled down while model calls were not. This measures scheduling, not code quality.
| Design | Completion p50 | Completion p95 | Cache-read tokens per run |
|---|---|---|---|
| Super-agent | 12.4 min | 15.7 min | 23.2 M |
| Super-agent without pass-through | 12.6 min | 15.5 min | 31.8 M |
| Single session, subagent tool, neutral prompt | 20.4 min | 29.5 min | 6.1 M |
| Single session, subagent tool, delegation-first prompt | 13.8 min | 29.0 min | 10.8 M |
Source: DeepSeek’s essay, as reported by Kingy AI and Dataconomy. Team-reported, not independently reproduced.
Three findings stand out to me.
On cost, DeepSeek’s argument is that this design only makes economic sense with cheap, fast models. Cache reads multiply, and on flash-tier pricing that stays affordable. On frontier pricing it gets expensive fast. Missing from the evaluation: real tasks, code correctness, accepted PRs, human review time, notification load and adversarial tests. Those are the numbers a bank would actually need.
The repository passed 17,000 GitHub stars in under four days. Stars are not deployments, so here is what you get if you clone it.
What it does. It watches one GitHub repository and, optionally, Feishu. When an allowed person asks for work, it opens a Ticket, runs it in its own DSH session and directory, and answers in the original conversation, usually with a pull request. A local web panel shows what needs a human. Setup is long enough that the README tells you to have a coding agent walk you through SETUP.md. The docs are numbered 000 to 008, from philosophy to a cookbook for adding a new Source, and they are the best part of the release.
Requirements. Node.js 22.19+ or 24+, Git 2.32+, Python 3.8+, tmux and GitHub CLI 2.48+, plus a compatible DSH version (^0.2.1-alpha.2). In practice it is POSIX-only. Community reports show native Windows needs patches, or WSL.
The warnings that matter:
danger-full-access as your OS user. Separate directories are not isolation. The deployment guide recommends a dedicated OS account. I would add a dedicated VM.None of this is a scandal. DeepSeek said clearly that much of this code was written by coding agents and is research code. It is a reference to read and learn from, not a product to install on Monday.
If you followed my series on prompt, context and harness engineering, this release is the third layer made concrete. The model is a commodity input. What decides speed, cost and safety is the system around it.
.env file. The essay itself admits credentials can end up in model context during normal work.Not really, and that is fine. Supervisor and worker patterns, event sourcing, background jobs and watchdogs are decades old. Anthropic published the brain/hands separation, and DeepSeek credits it. Hosted coding agents already turn an issue into a PR. What is new is a lab publishing the whole operating model in the open: the domain model, the authorization rules, the experiment, the failures, under MIT. That makes it the most useful reference document on multi-agent operations I have read this year.
The pattern fits a regulated dev team well, as long as you put the controls where the design already leaves room for them. Here is a fictional but realistic walkthrough.
The setting. A twelve-person team maintains the portfolio reporting service of a private bank. A Super-agent-style system watches their Git repository and the internal support channel used by the relationship-manager helpdesk.
auto.What the agent never gets in this story: production credentials, real client data, merge rights or a change-management approval. Those stay human.
dsh-superagent-prototype as a reference design. Rebuild the pattern on your approved agent platform, or harden a fork after a full security review.ignore. Never open an explicit-request cell on a broad channel.observe. Switch to auto per rule, only after reviewing a real sample of logged decisions.DeepSeek did not ship a product. It shipped an operating model for agents, with its trade-offs, its numbers and its open problems on the table. The lesson for anyone building internal agent platforms is simple: stop optimizing the conversation with one agent, and start designing the system that spares your people from having many conversations at all.
Read the essay. Read the numbered docs in the repo, in order. Then steal the four ideas that matter, in this order: a deterministic gate, Mandates that separate context from authority, observe before auto, and a Router that cannot do the work itself.
I would love to hear from teams who try this pattern in a regulated environment. What would you put in front of the gate?