
Google released Gemini 4 Hydrogen on November 12, 2026. It is the third Gemini 4 model after Argon and Carbon, and the one most people will use without ever picking it: it now runs the AI features of Google Search worldwide and sits behind the free Gemini app’s automatic model selection. For developers, it costs $1.50 per million input tokens and $7.50 per million output tokens.
My read, after going through Google’s three launch posts, the Cloud developer guide and the first independent numbers: Hydrogen is an excellent execution model, priced like a mid-tier model, and designed to work under a bigger planner. If you file it next to Claude Haiku 5.5 or GPT-6 Luna because it replaces a “Flash”, you will misjudge it. Its real competitors are Claude Sonnet 5.5 and GPT-6.1 Terra.
This article is layered. Developers get the spec sheet and the migration traps. Architects get the Orchestrator pattern. Decision-makers get the pricing, lifecycle and data questions.
Hydrogen started as a rumor. On October 27, an X post claimed that Gemini 4 Flash was in internal testing under the codename Hydrogen. On November 4, other accounts claimed five Hydrogen checkpoints running at 300 to 500 tokens per second, with no screenshot and no model ID. On November 11, Business Insider reported that Google staff were testing a “fast” model named Hydrogen on Jetski, Google’s internal development platform. The next day, Google shipped it.
| Pre-launch claim | What Google shipped |
|---|---|
| Hydrogen is the codename of the Gemini 4 Flash tier | Hydrogen became the product name; Google’s posts never say “Gemini 4 Flash” |
| 300 to 500 tokens per second | No tokens-per-second figure from Google; Artificial Analysis measures about 188 |
| Release around November 18 | Released November 12 |
| Five checkpoints in A/B tests | Not addressed by Google |
The name was right, the speed figure was unverifiable, and the date was off by six days. The number that actually matters for your budget, the price, never leaked. Worth remembering the next time a leak thread goes viral in your feed.
All of this comes from Google’s Cloud developer guide and the AI Studio model page.
| Item | Gemini 4 Hydrogen |
|---|---|
| Model ID | gemini-4-hydrogen, generally available, one stable version |
| Context window | 1,048,576 tokens, shared by input, thinking and output |
| Output per request | 65,536 tokens per segment; up to the full window with “long decode” (v1beta1 API only) |
| Thinking levels | low, medium, high (default), xhigh |
| Inputs | Text, image, audio, video, PDF, plus Word, PowerPoint, Excel and OpenDocument files |
| Output | Text only: no image generation, no audio generation, no Live API |
| Tools | Function calling, structured output, code execution, computer use, file search, URL context, grounding with Google Search and Maps |
| Caching | Implicit only, on shared prefixes of 4,096 tokens or more; cached input discounted 95% |
| Regions on Google Cloud | global, us, eu |
| Lifecycle | Short-term GA release, minimum 45-day retirement notice |
Two lines in that table deserve attention. Native Office file input means you can pass a .docx contract or an .xlsx budget straight into a tool result without a conversion step. And “short-term GA” means Google already tells you this model will be replaced, with as little as 45 days of warning.
Google’s pricing page only makes sense when you look at the whole family and its scheduled changes.
| Model | Input ($/1M tokens) | Output ($/1M tokens) | Scheduled change |
|---|---|---|---|
| Gemini 3.5 Flash-Lite | 0.30 | 2.50 | None listed |
| Gemini 3.8 Flash | 0.75 | 3.75 | 1.50 / 7.50 from January 1, 2027 |
| Gemini 4 Hydrogen | 1.50 | 7.50 | None listed |
| Gemini 4 Argon | 2.00 | 10.00 | 4.00 / 20.00 from December 1, 2026 |
| Gemini 4 Carbon | 2.00 | 10.00 | 4.00 / 20.00 from December 1, 2026 |
The other modes: Batch and Flex at $0.75 / $3.75, Priority at $2.70 / $13.50, cached input at $0.075. There is a free API tier with rate limits, and the pricing page states that free-tier content is used to improve Google’s products while paid-tier content is not.
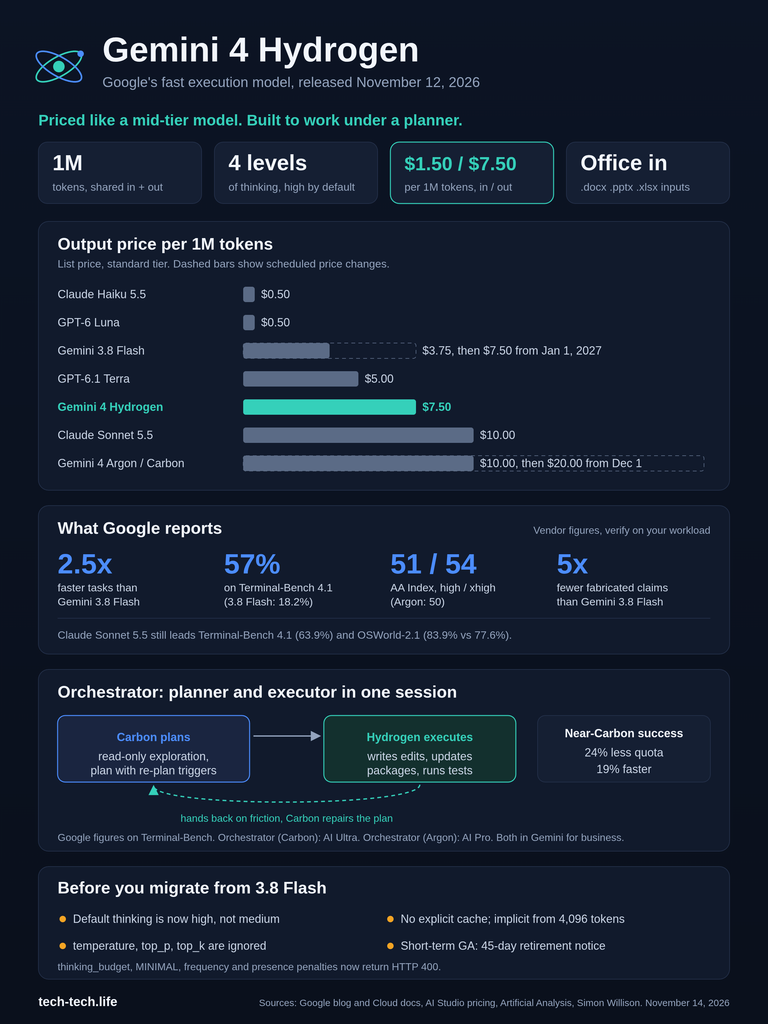
Here is the part most launch coverage skipped. Today, Hydrogen is only 25% cheaper than Argon and Carbon, as Simon Willison noted. On December 1, the gap becomes 75%. On January 1, Gemini 3.8 Flash will cost exactly what Hydrogen costs. Google is re-pricing the whole ladder around Hydrogen, and by January, staying on 3.8 Flash saves nothing. If you own an AI budget, model your Q1 2027 bill this month.
The Search rollout is the quiet headline. Robby Stein, VP of Product for Search, calls it the biggest model upgrade Search has had, with better handling of multi-part questions, a wider query fan-out and more tables and visual answers. For a lot of people, Hydrogen is about to become what an “AI answer” looks like.
Most of the figures in circulation are Google’s own. Here is what Google’s announcement and the Antigravity post claim:
On the independent side, Artificial Analysis measures about 188 output tokens per second, and an average of 1.3 minutes per index task at low against 13.7 minutes at xhigh, as reported by kie.ai. On that same index, Hydrogen at xhigh sits one point under Claude Sonnet 5.5 and GPT-6.1 Sol at their maximum settings (54 against 55).
Three things to keep in mind before you quote any of this in a steering committee.
The thinking level matters as much as the model name. The flattering 54 is xhigh, the slowest and most token-hungry setting. The default high gives 51. Any comparison that does not say which level was used is not a comparison.
The widest margins sit on the softest benchmarks. Vending-Bench 2 reports a simulated bank balance, not a pass rate, and Epoch has reported grading weaknesses in the public tasks of Agents’ Last Exam. Hydrogen’s competitors keep their leads on the more established terminal and computer-use tests. The safety numbers come without a named baseline, so treat them as claims to verify on your own workloads.
Fast and cheap shows up in the output. Simon Willison ran his “pelican on a bicycle” test across the three Gemini 4 models. At the high level, Hydrogen produced its drawing in 19 seconds for about 4 cents. Argon took about two and a half minutes for 17 cents, Carbon about four minutes for 20 cents. Hydrogen’s pelican was also visibly plainer. For agentic loops where each step is small and verifiable, that trade is excellent. For open-ended creative or design work, the bigger siblings still earn their price.
Start with list prices, standard tier, per million tokens. Third-party pricing pages were used for the non-Google models.
| Model | Input ($/1M) | Output ($/1M) | Where it sits |
|---|---|---|---|
| Claude Haiku 5.5 | 0.10 (up to 100K context) | 0.50 | Budget tier |
| GPT-6 Luna | 0.10 (up to 272K context) | 0.50 | Budget tier |
| GPT-6.1 Terra | 1.00 | 5.00 | Mid tier |
| Gemini 4 Hydrogen | 1.50 | 7.50 | Fast execution tier |
| Claude Sonnet 5.5 | 2.00 | 10.00 | Mid tier |
Per token, Hydrogen costs 15 times what Haiku 5.5 and GPT-6 Luna cost. That one ratio settles the positioning question: Hydrogen is not competing for your classification and routing traffic. It is competing for the agentic work you currently send to Sonnet 5.5 or Terra.
On that ground, Google’s own model card puts Hydrogen next to Claude Sonnet 5.5. Selected rows, vendor-reported:
| Benchmark | Gemini 4 Hydrogen | Claude Sonnet 5.5 |
|---|---|---|
| SWE-sweep (repository bug fixing) | 13.5% | 3.1% |
| Agents’ Last Exam v1.1 | 71.6% | 60.4% |
| AutomationBench-AA | 76.1% | 71.8% |
| Terminal-Bench 4.1 | 57.0% | 63.9% |
| OSWorld-2.1 (computer use, offline subset) | 77.6% | 83.9% |
| Terminal-Bench-Science 0.1 | 51.4% | 59.9% |
On the full ten-row card, Hydrogen wins seven, and GPT-6.1 Terra scores 5.8% on SWE-sweep. Sonnet 5.5 keeps the terminal and computer-use rows. Artificial Analysis estimates that running its index costs about a third as much on Hydrogen as on Sonnet 5.5.
My practical mapping:
The most important announcement on November 12 was a dropdown entry in Google Antigravity called Orchestrator, which pairs Hydrogen with Carbon (or Argon) inside a single agent session.
The Antigravity team describes the flow like this. Carbon starts in a read-only phase: it explores dependencies, resolves ambiguities and writes a plan with explicit re-planning triggers. Hydrogen takes over to write the edits, update packages and run the tests. When Hydrogen hits friction, it hands the task back to Carbon, which inspects the state, repairs the plan and lets execution resume. Google reports near-Carbon success rates with 24% less quota and 19% faster completion on average. One detail for the careful reader: the main announcement attributes these figures to Terminal-Bench 4.0, the Antigravity post to Terminal-Bench 4.1.
Google explicitly contrasts this with the static model router most of us have built: guess the difficulty from the first prompt, then send the whole task to the cheapest model that seems good enough. That approach breaks on long-running agents, because difficulty changes during the task. Orchestrator switches in both directions, as many times as the trajectory needs.
If you have followed my writing on the AI software factory, this is the pattern I keep coming back to: a frontier model for judgment, a fast model for volume, and an explicit hand-off contract between them. Google turned it into a product feature. You can build the same thing with any pair of models, and the Antigravity SDK lets you assign Hydrogen and Carbon to roles in code. Orchestrator (Carbon) is for Google AI Ultra subscribers, Orchestrator (Argon) for Pro, and enterprises get both through Gemini for business.
Moving from Gemini 3.8 Flash takes more than a model ID change. From the developer guide:
Gemini 4 Hydrogen is the best cost-adjusted execution model Google has shipped, and for many agentic coding and document workflows it is now the default to beat. Just do not let the word “Flash” in the leaks set your expectations on price: it is a mid-tier model in cost, a strong worker in practice, and at its best when a bigger model does the planning. The real story of this launch is Orchestrator, and the teams that adopt the planner-executor pattern will benefit whichever vendor wins next quarter.
