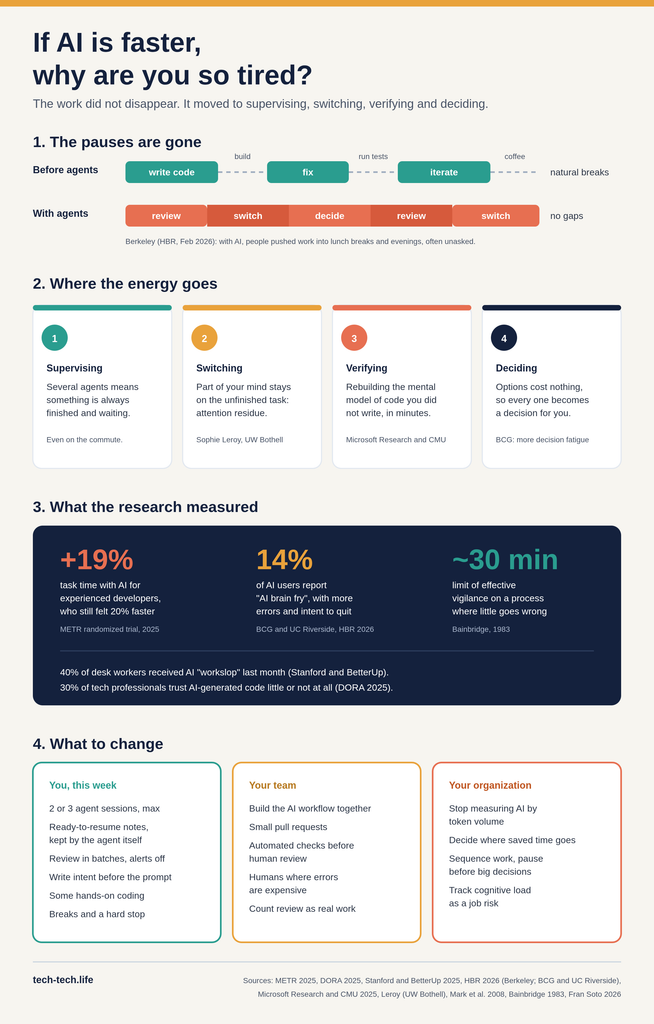

The work did not vanish when the agents arrived. It changed shape, and the new shape is harder on the brain than it looks.
I spend a large part of my week helping developer teams adopt generative AI. I run the internal trainings, I field the “which tool should we standardize on” debates, and I use Claude Code and GitHub Copilot every day. Enthusiasm is part of my job description.
And yet the question I hear most often after a session has nothing to do with prompts or models. It sounds like this: “I ship more than I ever did. So why am I empty by four in the afternoon?”
Fran Soto asked the same thing in a recent issue of the Strategize Your Career newsletter, and the answer there is a good starting point: the effort moved from typing code to reviewing it, switching between agents and making decisions for them. I agree with that diagnosis. I also think it stops too early. Over the last eighteen months, researchers at METR, Berkeley, BCG and Google’s DORA team have published data that explains much of what developers feel, and a 1983 paper on factory automation explains the rest.
This article connects the two: what developers report, and what the evidence says about why. Then it gets practical, with what I now tell teams to change, from the individual developer up to the organization that sets the pace.
The tiredness is not in your head. Six studies, published between early 2025 and spring 2026, point in the same direction from different angles.
| Study | Who and how | What it found |
|---|---|---|
| Bedard et al., BCG and UC Riverside, HBR, March 2026 | Survey of 1,488 full-time US workers in large companies | Named “AI brain fry”: mental fatigue from using or overseeing AI tools beyond your cognitive capacity. 14% of AI users reported it, with more errors, more decision fatigue and a higher intent to quit. Software development ranked among the most affected roles. |
| Ranganathan and Ye, UC Berkeley, HBR, February 2026 | Eight months of fieldwork in a 200-person US tech company | People worked faster, took on tasks outside their role and spread work into evenings and breaks, often unasked. The authors call it workload creep and link it to fatigue and weaker decisions. |
| Stanford Social Media Lab and BetterUp, HBR, September 2025 | Survey of 1,150 US desk workers | 40% had received “workslop” (AI output that looks finished but is not) in the previous month. Each case took close to two hours to sort out. |
| DORA, State of AI-assisted Software Development, September 2025 | Nearly 5,000 technology professionals | 90% use AI at work and more than 80% feel more productive, yet 30% trust AI code little or not at all. AI amplifies a team’s existing strengths and weaknesses, and is still linked to more delivery instability. |
| METR randomized trial, July 2025 | 16 experienced open-source developers, 246 real tasks in their own repositories | With early-2025 tools, tasks took 19% longer. Developers had expected a 24% speedup and, after the slowdown, still believed AI had made them 20% faster. |
| Lee et al., Microsoft Research and Carnegie Mellon, CHI 2025 | 319 knowledge workers, 936 real use cases | Critical thinking shifts toward verifying output, integrating it and stewarding the task. The more people trust the AI, the less critical thinking they apply. |
Two signals come out of this table. The first is a perception gap. METR’s developers felt faster while being measurably slower, which tells me our sense of speed is a poor instrument. The study used early-2025 tools and its authors are careful not to generalize, but the gap between feeling and measurement is the part I would bet survives newer models.
The second signal is intensity. The Berkeley and BCG studies describe the same mechanism from two sides: AI makes it cheap to start things, so people start more of them, and the cost shows up later as attention spread too thin. Most of these numbers are self-reported, so treat them as strong signals rather than settled science. What convinces me is that a survey, an ethnography and a controlled trial land in the same place.
The words matter, because they lead to different fixes. Fatigue is the normal cost of a hard week and a weekend repairs it. Burnout is what months of chronic stress produce: exhaustion plus cynicism about the work plus a feeling of being less effective. It is a reason to talk to someone, not to install a new productivity app. AI brain fry sits between the two. It is acute, tied to a specific pattern of work (too many AI threads, too much oversight) which means it points at something you can change. The BCG authors are explicit that it is a distinct phenomenon from burnout, and the label is new enough that I use it as a useful description, not a diagnosis.
Picture an ordinary Tuesday in 2026. One Claude Code session is refactoring a payment module, a second is generating tests for a REST API, a third is drafting a database migration. You are in a meeting. Your phone shows that one of them is waiting for an answer. None of this feels like hard work, and all of it is draining you. Four costs hide in that picture.
Before agents, the job had built-in breathing room. You waited for the build, you waited for the test suite, you stared at a stack trace and went for coffee. Soto makes this point well: supervising never stops, because with several agents running there is always something finished and waiting. The agents keep working during your commute, so the temptation to check on them does too.
The Berkeley study saw the same thing at company scale: once starting a task cost one prompt, people slipped work into lunch, evenings and the minutes between meetings. The pauses did not disappear because someone took them away. We gave them up ourselves, one prompt at a time.
Sophie Leroy, who studies interruptions at the University of Washington Bothell, coined the term attention residue: when you move from task A to task B, part of your mind stays with A, and your performance on B drops, especially when B is demanding. The residue is worst when A is unfinished and you know you will have to rush back to it.
That is an exact description of running parallel agents. Every session you leave is unfinished by design. Soto admits to asking each agent “where are we and what is left?” several times a day, and I recognize myself in that. The agent is not confused. I am, because I carry four half-loaded contexts in my head.
Gloria Mark’s lab at UC Irvine found something uncomfortable back in 2008: interrupted people complete tasks faster, but they report significantly more stress, frustration, time pressure and effort. Speed and strain rise together. That is a decent one-line summary of agentic development today.
Reviewing your own code is cheap because you built the mental model while typing it. Reviewing an agent’s diff means building that model from zero, in minutes, for code whose intent you have to reverse-engineer. If you did not specify the intent clearly up front, you do that thinking during review anyway, under time pressure.
The Microsoft and Carnegie Mellon study describes this shift precisely: AI reduces the effort of producing work and increases the effort of verifying, integrating and taking responsibility for it. It also found a trap. The more people trust the AI, the less critically they review. So a tired reviewer faces two bad options: spend energy they no longer have, or wave the diff through.
When generating an option costs nothing, you get more options. Three approaches to the migration, two versions of the test plan, a suggestion to refactor a neighbouring module while the agent is at it. Each one is a small decision, and each decision lands on you. The BCG researchers measured this directly: workers with brain fry reported more decision fatigue and more mistakes, both minor and serious.
Add it up and the day gets denser without getting longer. You work the same hours, but more of them are spent at full cognitive load, with fewer of the low-intensity moments that used to let the brain recover.
Every big jump in programming productivity came from an abstraction we could stop thinking about. I never read the assembly my compiler produces, and I do not need to, because the compiler is deterministic. Same input, same output, every time.
An AI agent also lifts us up a level of abstraction, but it leaks. Even with a good spec, solid skills files and a disciplined workflow, the agent can take the code somewhere you did not intend. So you keep descending to the line level to check. You get the stress of being a manager and the stress of being a reviewer in the same day.
None of this is new to people who study automation. In 1983, the cognitive psychologist Lisanne Bainbridge published a five-page paper called Ironies of Automation, about operators in power plants and chemical factories. Two of her ironies describe the AI-assisted developer with uncomfortable accuracy.
The first concerns monitoring. Bainbridge cited vigilance research showing that even a highly motivated person cannot keep effective attention on a source where very little happens for much more than half an hour. Her conclusion was blunt: watching for rare abnormalities is humanly impossible to do well, so it has to be handed to automatic alarms. Now think about reviewing the twentieth agent diff of the day, where nineteen were fine.
The second concerns skill. An operator who only monitors gets less practice, so when the automation fails, the person expected to take over is less able to do it. The developer who has not written concurrent code by hand in six months is the one asked to spot the subtle race condition in the agent’s output. The better the agent gets, the rarer its mistakes become, and the harder they are to catch.
This is why “just review more carefully” is not a strategy. A reader under Soto’s post, Andrii Tretiak, described what worked for him after a year of agentic work: he stopped reading every diff line by line, moved that work to separate automated checks, and now reads the findings, going into the code himself only where a mistake would be expensive. That is Bainbridge’s advice applied forty years later. You keep human attention for the places where it pays, and you build alarms for everything else.
I work in banking IT, and this is where the fatigue question stops being a wellbeing topic and becomes an operational risk.
In a startup, an exhausted developer who rubber-stamps an agent’s pull request ships a bug. In a regulated institution, the same signature sits in an audit trail. Four-eyes review, segregation of duties and change management exist so that a named human is accountable for what reaches production. Agents multiply the number of changes that need that signature. They do not multiply the number of reviewers, or the hours in their day.
Regulators already assume that a tired human will over-trust a machine. Article 14 of the EU AI Act requires that people overseeing high-risk AI systems remain aware of automation bias, the tendency to rely too much on automated output. Legal scholars have noted that it is the only cognitive bias the Act names explicitly. A coding assistant is not a high-risk system under the Act, but the logic carries over to any team whose job is to sign off on machine output. If you work for a European group, as many engineering teams here in Tunis do, expect auditors to ask how your developers review AI-generated code, and whether that review is real.
The uncomfortable part is that the code where review matters most, such as payment flows, access control and regulatory reporting, gets its share of agent-generated changes too, and the people who review it are as tired at the end of the day as everyone else.
What I push for in this context:
Soto proposes three habits: limit open tasks, take scheduled breaks, and set a hard stop to the day. I use all three and recommend them. They treat the symptoms an individual can reach. The research says the causes also sit in how teams review and in what organizations expect, so the playbook below works at three levels.
Because the agents took the part of the job that let you rest and left you the part that never does. Typing code was slow, but it was low-intensity work with built-in pauses. Judging code, switching contexts and making decisions is the most expensive work a brain does, and the tools now let you do it all day long.
The AI is faster. Your attention is not, and it does not scale with the number of terminal tabs you open. Generation now runs ahead of comprehension, and the gap between the two is where the fatigue comes from.
I still want every developer I train to use these tools. I also want them to measure success by the amount of good work they can sustain for a year, not by how much they can generate in a week. That means fewer parallel threads, reviews backed by machines, intent written before the prompt, and organizations that decide where the saved time goes. If the tiredness lasts for months and comes with cynicism about the work, it is no longer brain fry, and it deserves a conversation with someone you trust.